Local AI
Run the AI on your own computer and chat in Producer Pal's built-in chat window: free, private and offline, but less smart than online AI. Two apps can run it: Ollama (the easiest) or Bionic / LM Studio.
Needs a powerful computer
An Apple Silicon Mac with lots of memory, or a PC with a strong Nvidia graphics card (8 GB of video memory at least, 16 GB or more is better). See Running Locally to check yours. On a regular laptop, use an AI router instead.
What You Need
Ableton Live 12.3+ with Max for Live. Live 12.4 or later is recommended. On Live 12.3 these don't work:
- writing clip automation (reading and clearing it still work)
- loading a sample into Simpler
- the Library tool (searching your library and listing plug-ins)
- finding a preset by name outside a device's own presets (packs' drum kits, Sounds racks, custom folders)
- opening a plug-in's editor window
Use the version of Max bundled with Live, or make sure your standalone Max is up to date.
1. Install the Max for Live Device
Download Producer_Pal.amxd, the Producer Pal Max for Live device.
Open User Library (under Places) in Live's browser, go to Presets → MIDI Effects → Max MIDI Effect, and drag Producer_Pal.amxd into that folder:
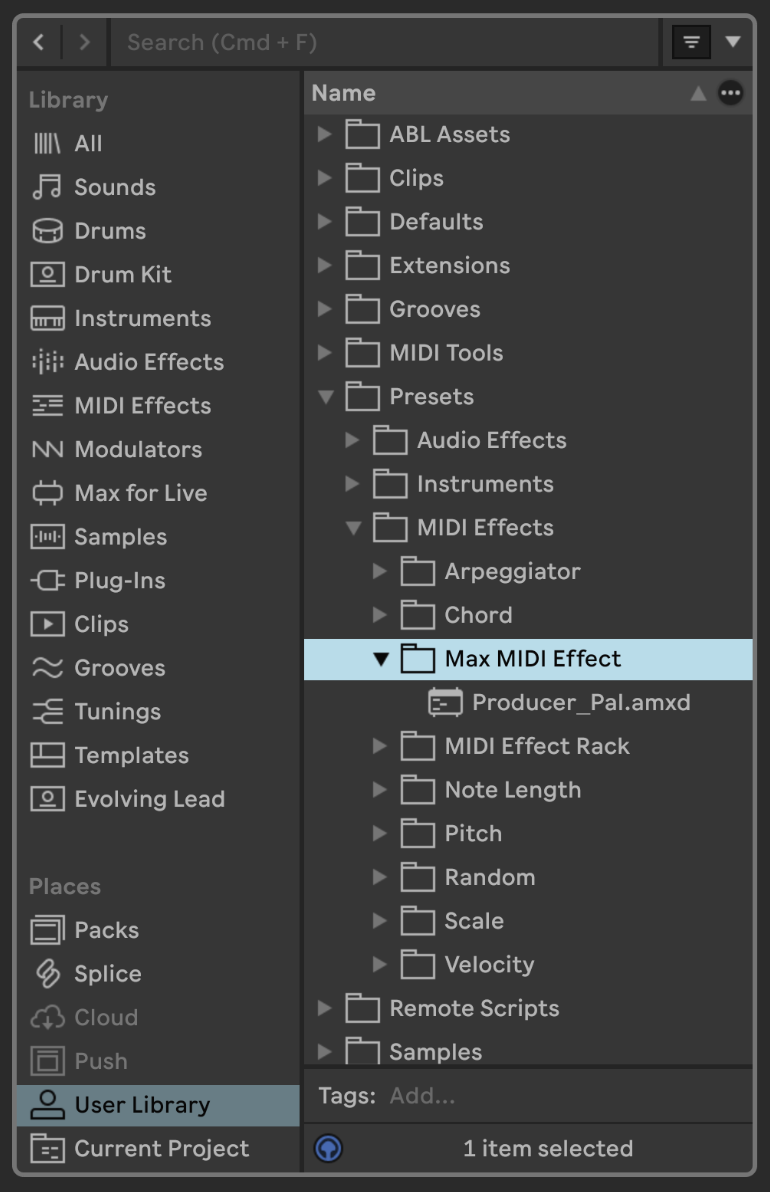
Drag it from the Max MIDI Effect folder onto a MIDI track:
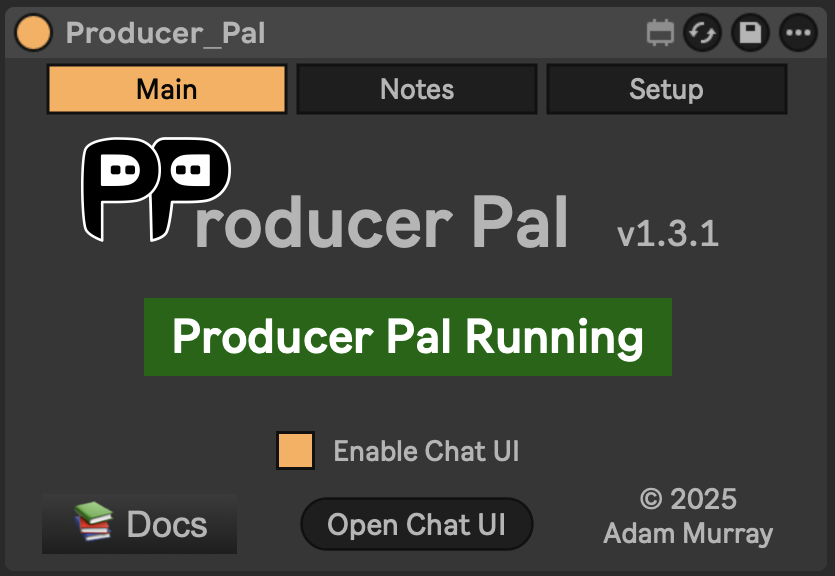
It should display "Producer Pal Running" or something isn't working.
Then finish the installation: click Finish installation… on the device (or Open Chat UI, then Settings → Installation), and click Install there to add the remote script (clip automation, undo, plug-ins).
Restart Live, then choose Producer Pal as a Control Surface in Settings → Tempo & MIDI, with Input and Output left as None.
More in Finish the Installation.
2. Set Up Ollama or Bionic / LM Studio
Pick one.
Ollama
Haven't installed the device yet? Do step 1 first.
Download and install Ollama.
Download a model that can control other apps (Ollama calls this "tools"), such as
qwen3.8,gemma4,muse-glimmerormistral-small3.2. Open Terminal (Mac) or Command Prompt (Windows), type this and press Enter:ollama pull qwen3.8Swap in another name to get a different model. If your computer can handle it, a bigger version of a model is smarter. Browse more models that support tools.
Open the Ollama app's settings and set Context length to 16k or higher. Producer Pal's instructions don't fit in the default, and the AI can't use Producer Pal without them. (Running Ollama without the app? Set
OLLAMA_CONTEXT_LENGTH=16384instead.)Settings to use in step 4:
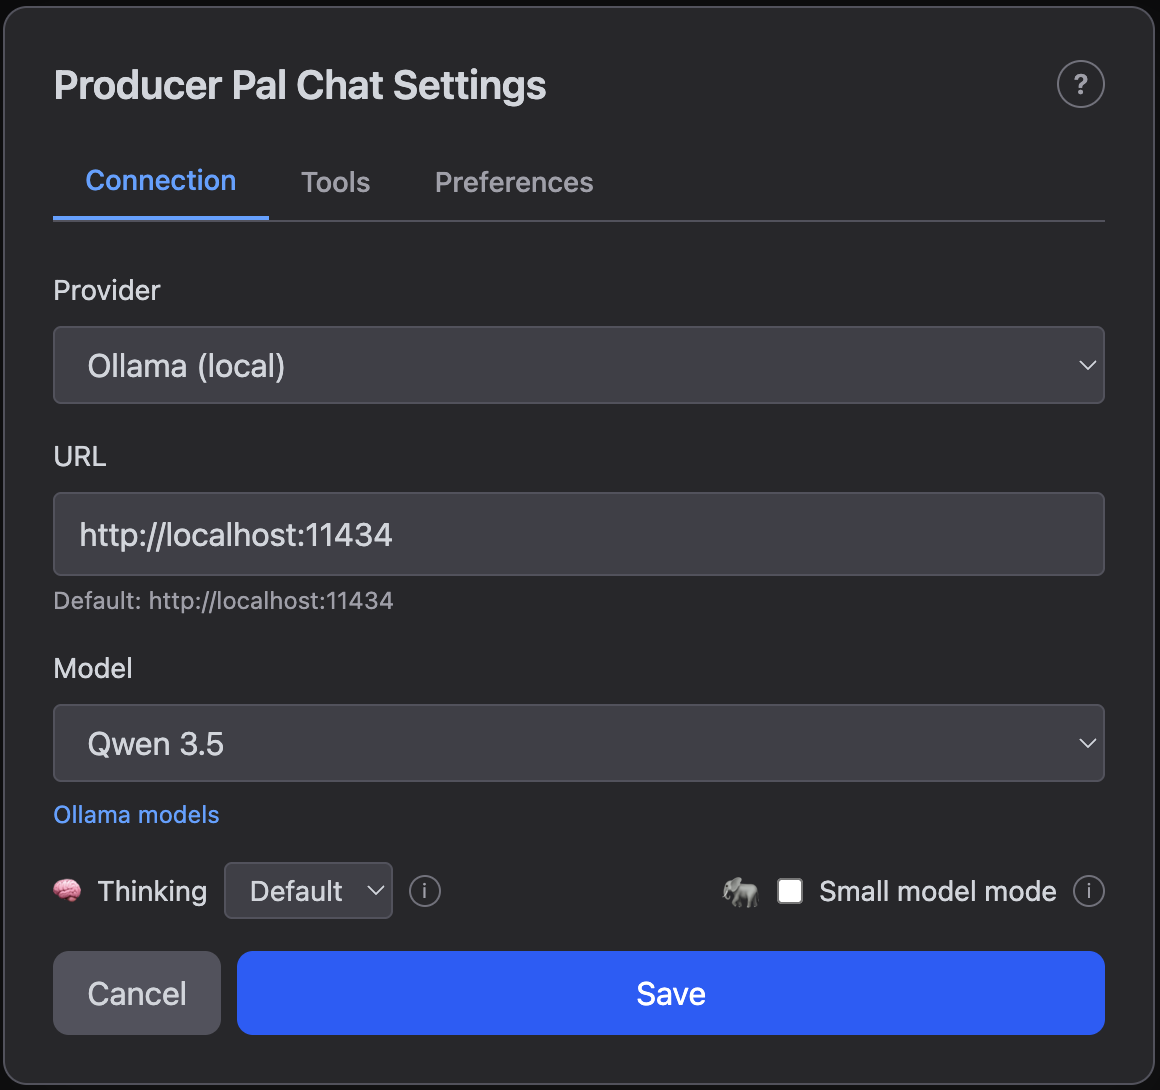
- Provider: Ollama (local)
- URL: leave it as
http://localhost:11434(to run Ollama on another computer, see the user guide) - Model: the name you downloaded, like
qwen3.8
Bionic / LM Studio
Haven't installed the device yet? Do step 1 first.
This is for Bionic. The older LM Studio app also works: its menus differ, but the settings are the same. Prefer Bionic's own chat window? See Bionic / LM Studio as a desktop app.
Install Bionic (free, no account needed).
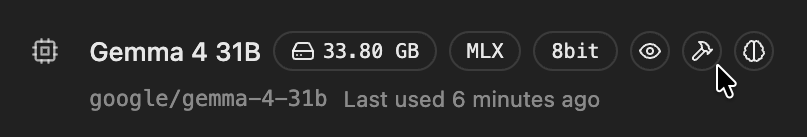
Download a model under Settings → Explore, such as a recent version of Qwen, Gemma, Mistral, or Nemotron. It has to support tools: under Settings → Library, a hammer icon marks the ones that do:
Go to Settings → Local Model API and turn on Local API server (it should then read "Running") and CORS (lets your browser talk to Bionic). Copy the Base URL while you're here (
http://localhost:1234/v1by default):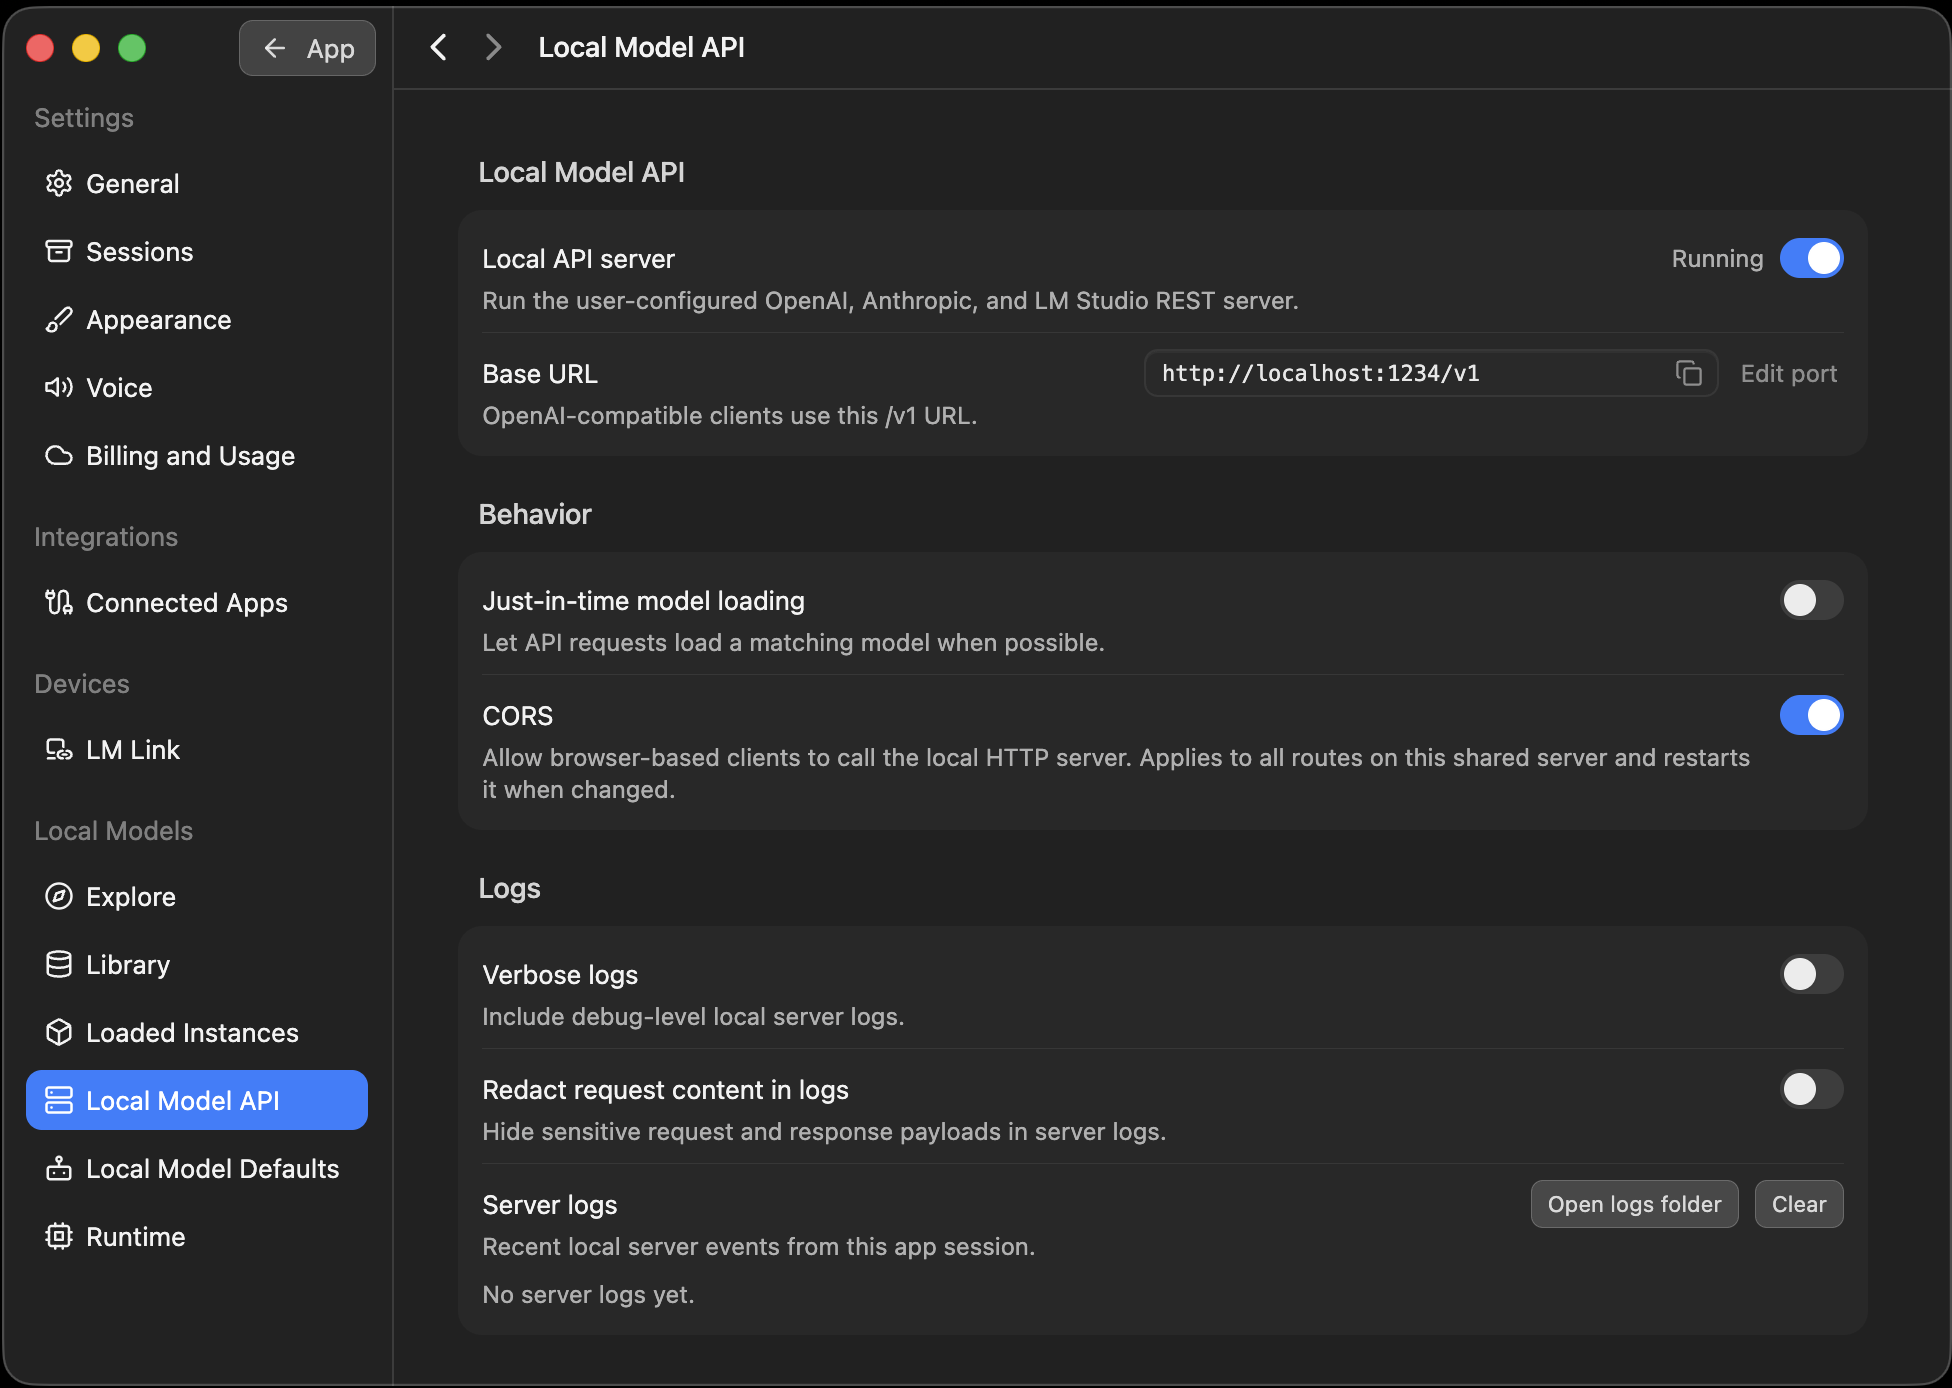
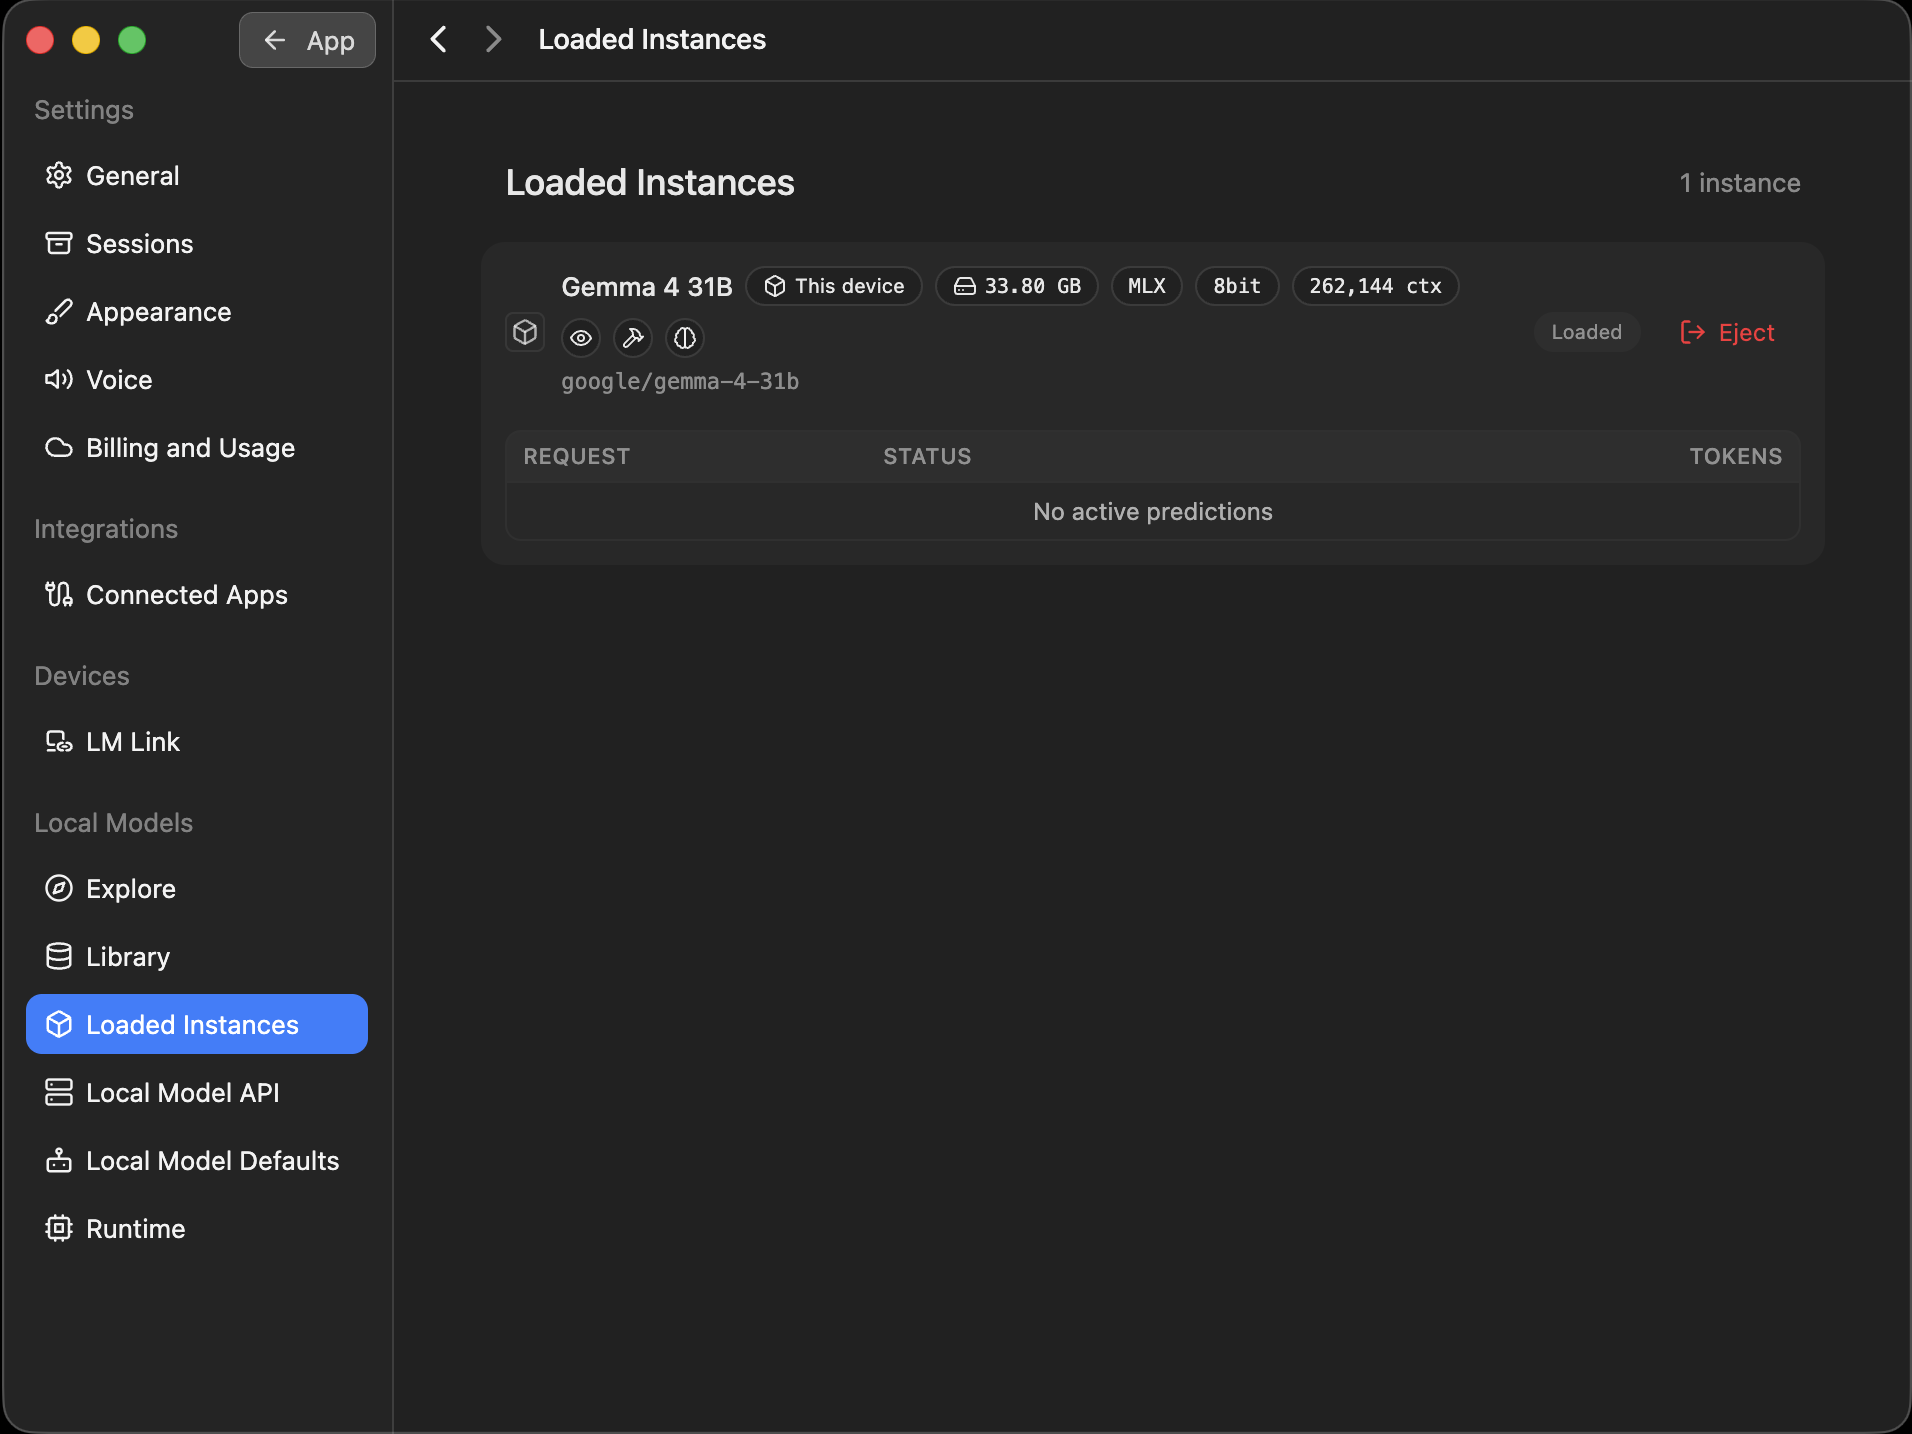
Turn on Just-in-time model loading, or load a model by having a quick chat with it in Bionic first. Set its context length to 16k (16000) or higher. Loaded models are listed under Settings → Loaded Instances:
Settings to use in step 4:
- Provider: Bionic / LM Studio (local)
- URL: the Base URL you copied
- Model: a model that supports tools, such as
qwen/qwen3.8-27b,google/gemma-4-e4b,mistralai/devstral-small-2-2512, orzai-org/glm-4.7-flash
3. Turn On Small Model Mode (Recommended)
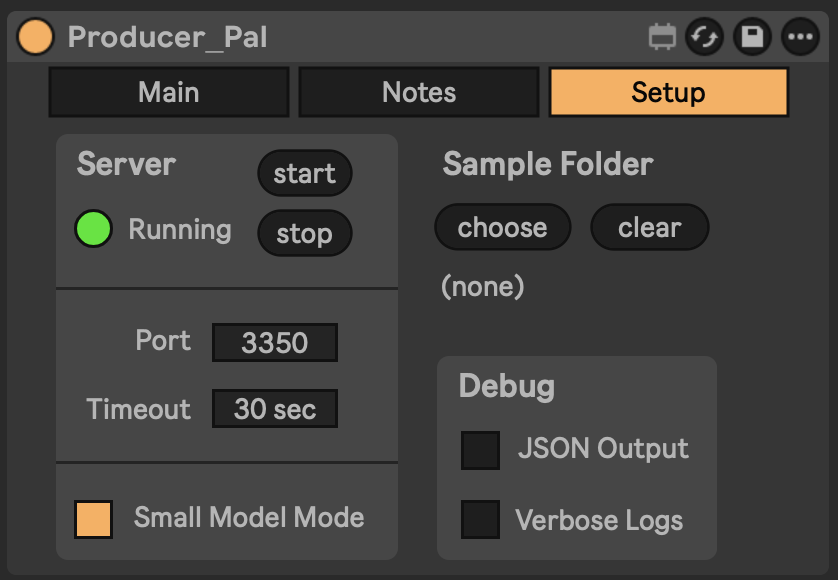
In the device's Setup tab, turn on Small Model Mode. It gives local AI a simpler set of tools.
4. Connect
- In the device, click "Open Chat UI". The chat opens in your browser, and so do its settings the first time.
- Fill in the settings listed above. For an online AI, paste your API key too. Then click "Save".
- Click "Quick Connect". It says "Connect to Ableton." for you:
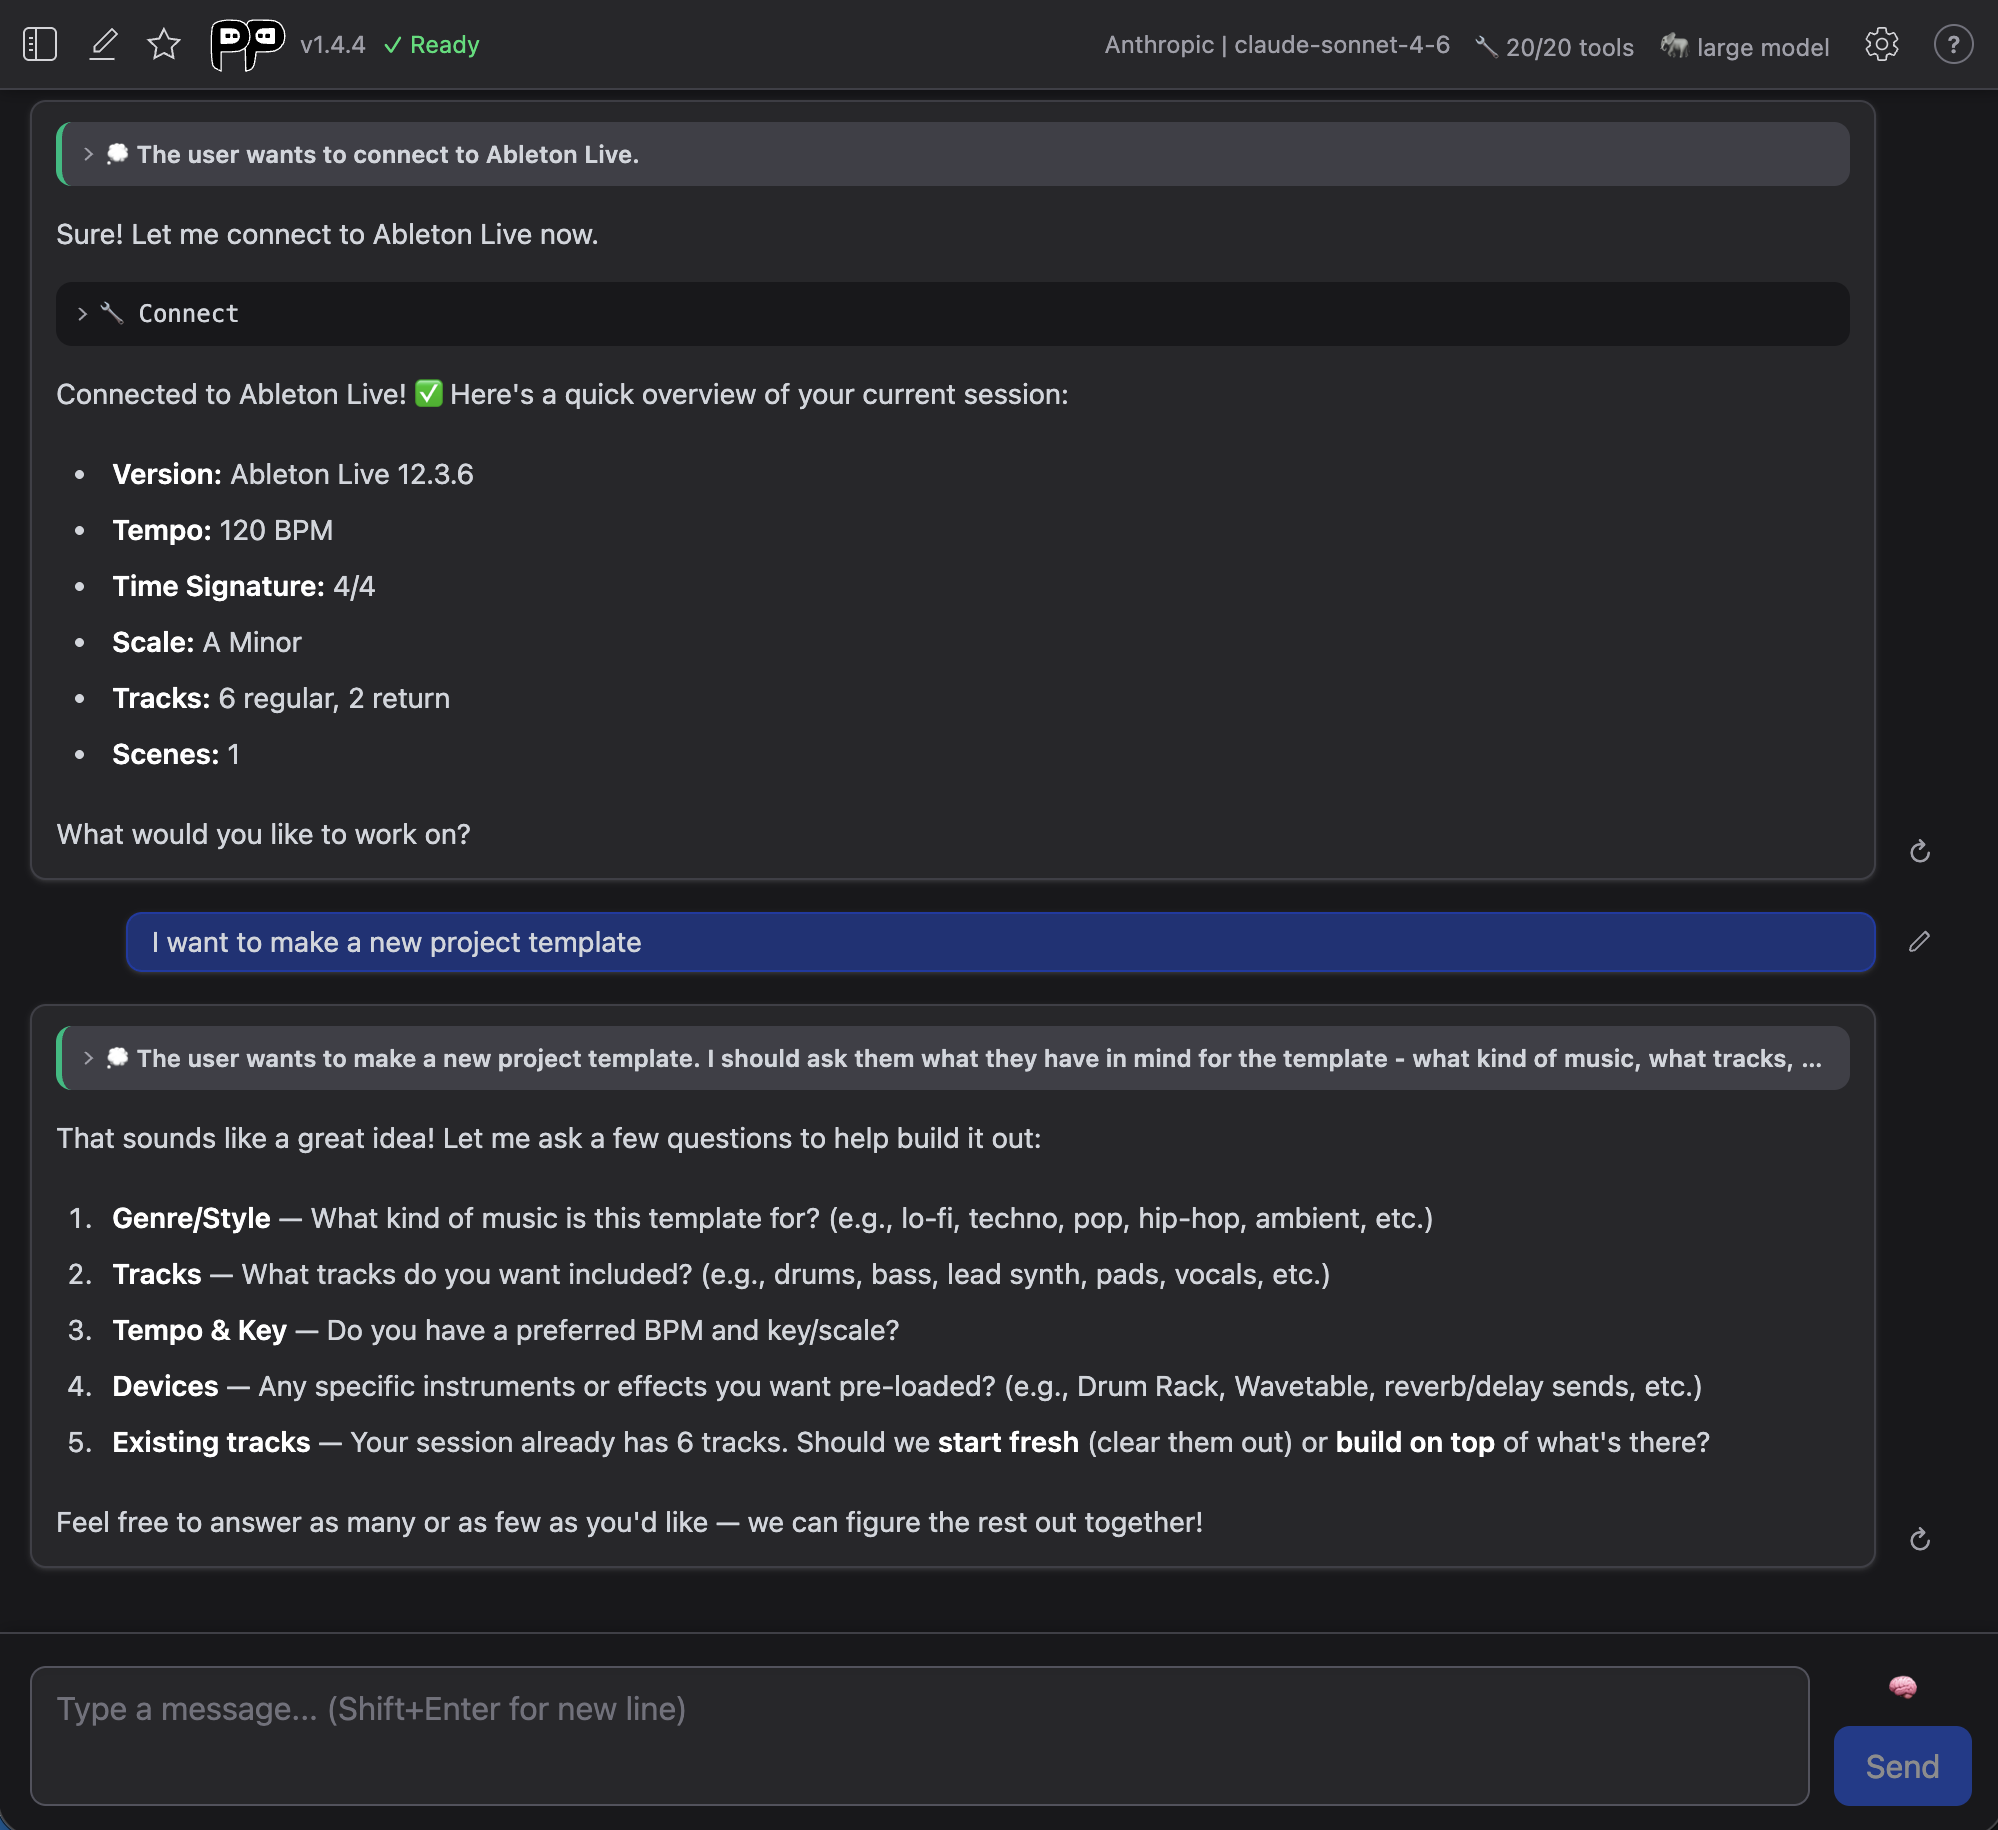
Check It Works
Once connected, the AI confirms it can see your Live Set. Try a first request that doesn't change anything:
What tracks are in my Live Set?
It should list your tracks. If it can't connect or gets something wrong, see Troubleshooting below.
Tips
- Set the context length to 16k (16000) or higher in the model's settings. This is how much the AI can keep in mind at once. About 8k is enough to connect and send a few messages. Higher is slower, so find the balance.
- Keep it simple: start from an empty Live Set and short material, like MIDI clips of 4 bars or less. Small models are told to delete and start over rather than make edits (other than simple additions).
- When it goes wrong, back up. Delete the last messages or edit your last message and try again, instead of trying to correct the AI.
- Close apps you don't need so the model gets more of your computer.
Troubleshooting
- Garbled text like
<|tool_call_start|>..., or it says it can't connect to Ableton: the model can't use tools. Pick another one from Ollama's tools list, or one with Bionic's hammer icon. - Ollama says the model isn't installed, but you downloaded it: enter the full name, including the part after the colon (like
muse-glimmer:30b-mlx). Typeollama listin Terminal to see the exact names. - Bionic's server isn't behaving: turn on Verbose logs under Settings → Local Model API, then read Server logs on the same page.
- The first reply is slow: that's normal. Later replies in the same chat are usually much faster.
For anything else, see the Troubleshooting Guide.